> For the complete documentation index, see [llms.txt](https://docs.scraperapi.com/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.scraperapi.com/integrations/automation-and-workflow-integrations/n8n-integration/scraperapi-crawler-n8n.md).
# Crawler <--> n8n
This page covers how to use the [ScraperAPI Crawler](/scraperapi-crawler-v2.0/introduction.md) within n8n. Through our official ScraperAPI n8n node, you can seamlessly initiate and manage crawler jobs directly from your workflow.
#### How it works
**Crawling Workflow**
1. Add a **ScraperAPI** node to your workflow.
2. Select the **Crawler** resource.
3. Choose the operation you want to run:
* Initiate a Crawler Job.
* Get Job Status.
* Cancel a Crawler Job.
4. Configure crawler settings:
{% tabs %}
{% tab title="REQUIRED" %}
* Start URL (where crawling begins).
* **Max Depth** and **Crawl Budget.**
* **URL Regex Include** (Regex pattern for URLs to include). You can then use tools like [regex101](https://regex101.com/) for debugging.
* **Callback Webhook URL** (where to stream the results).
{% endtab %}
{% tab title="OPTIONAL" %}
* **URL Regex Exclude** - Enter a Regex pattern to skip certain URLs. Any URL that matches this pattern will not be crawled.
* Schedule Interval - The interval at which the crawler will run: *Once, Hourly, Daily, Weekly, Monthly.*
* Schedule Name - Name of the crawler.
{% endtab %}
{% endtabs %}
{% hint style="success" %}
When defining parameters, you can choose the ***'Let the model define this parameter'*** and the connected AI model will automatically set the most appropriate value based on your prompt.
{% endhint %}
5. Configure any optional parameters (see available [Parameters](https://github.com/scraperapi/n8n-nodes-scraperapi-official/blob/master/README.md#parameters)).
#### AI Chat Model Scraping Workflow
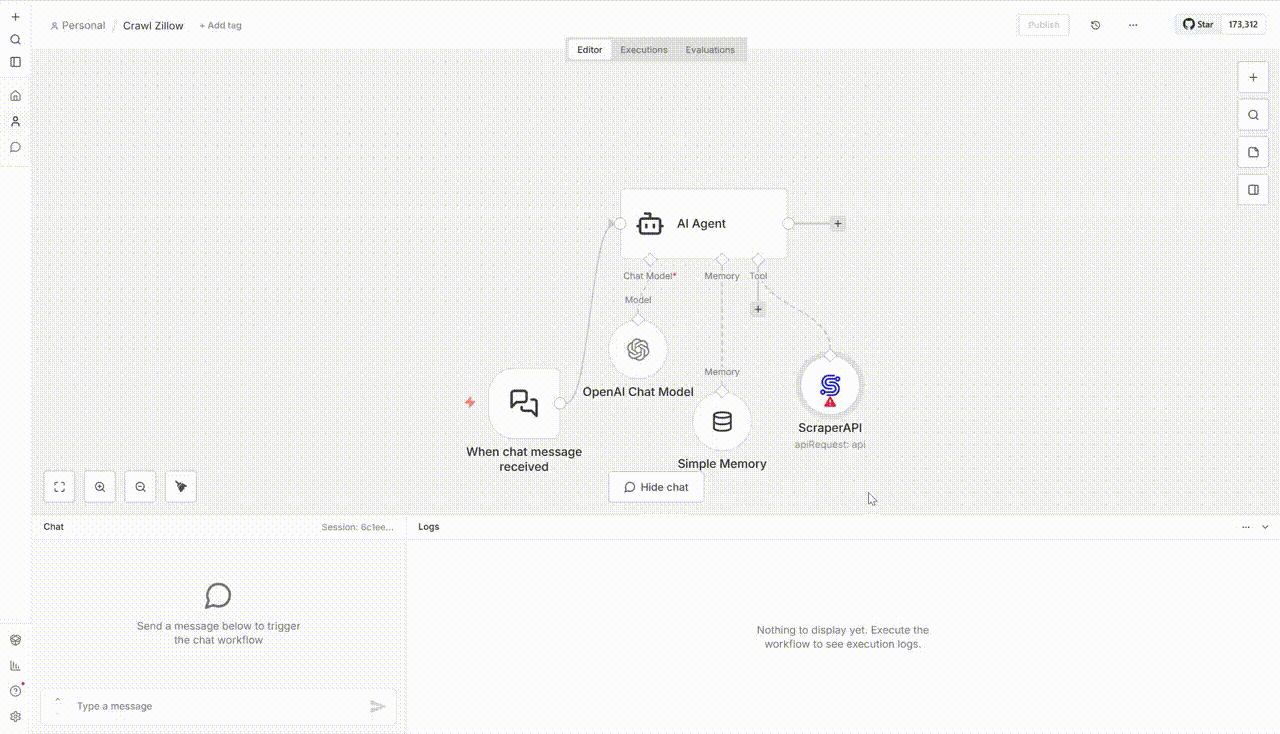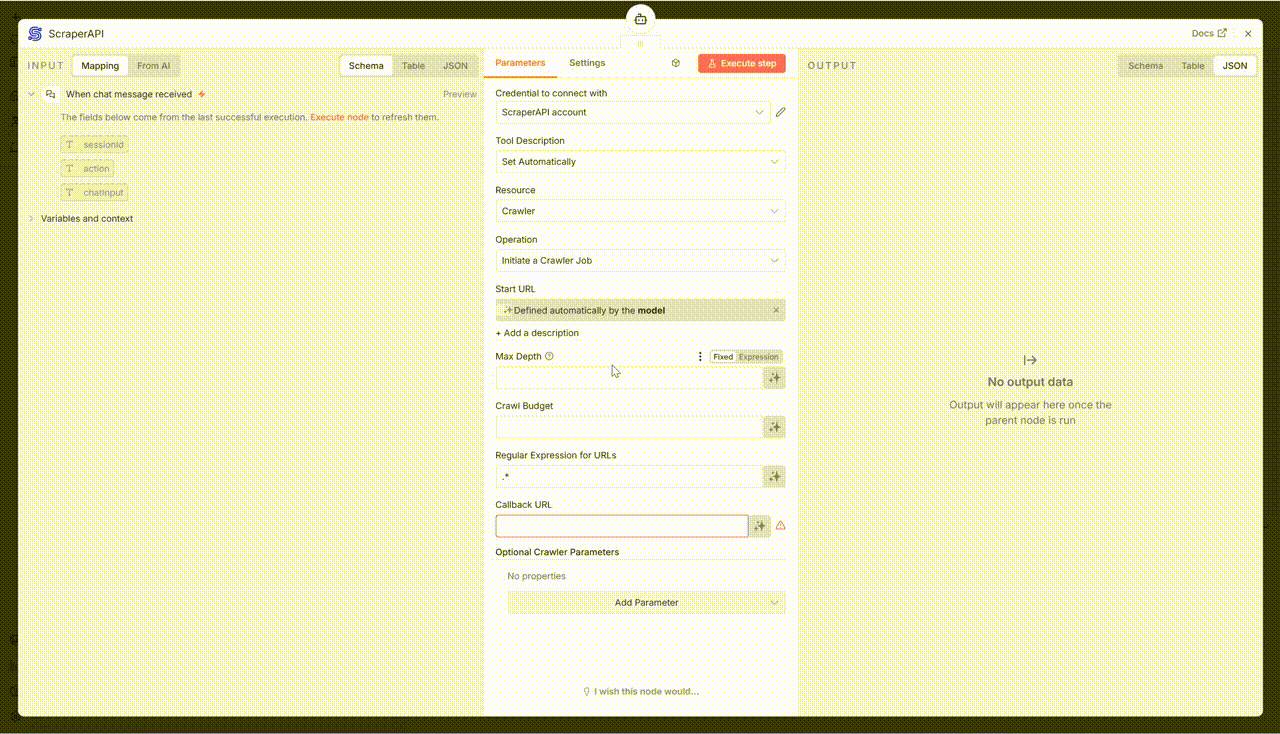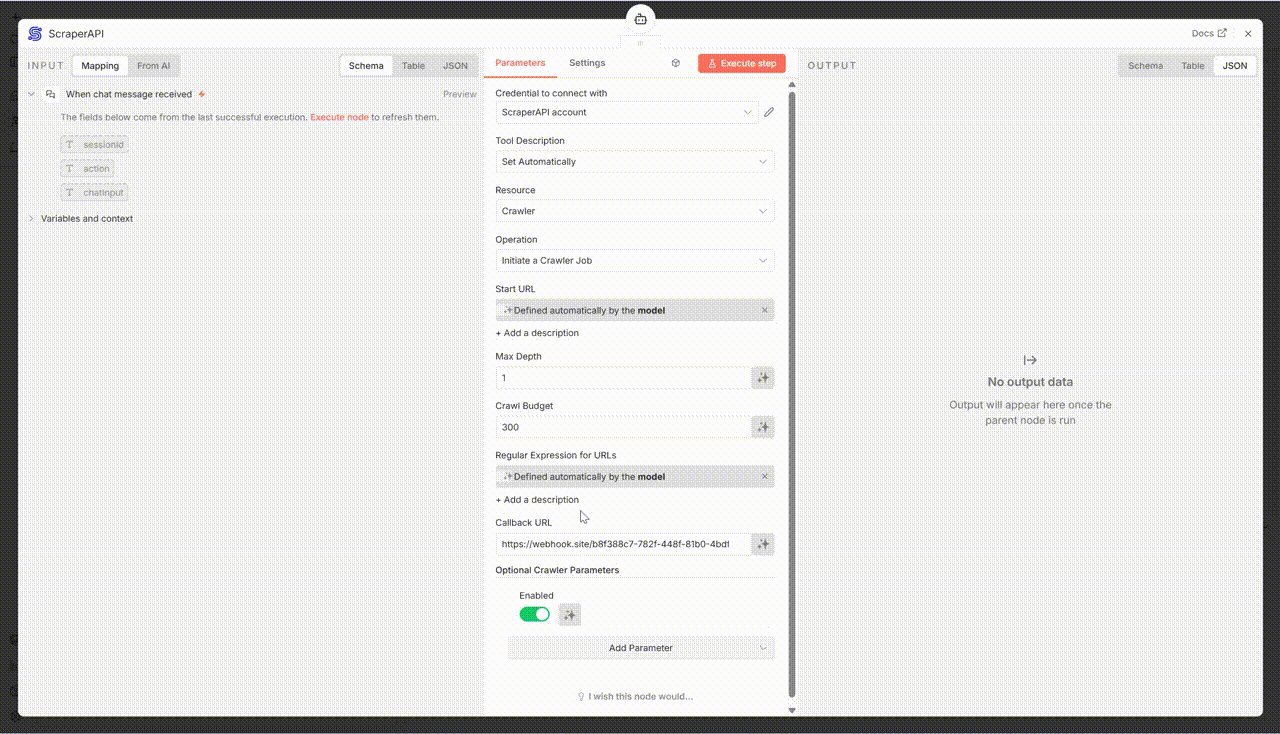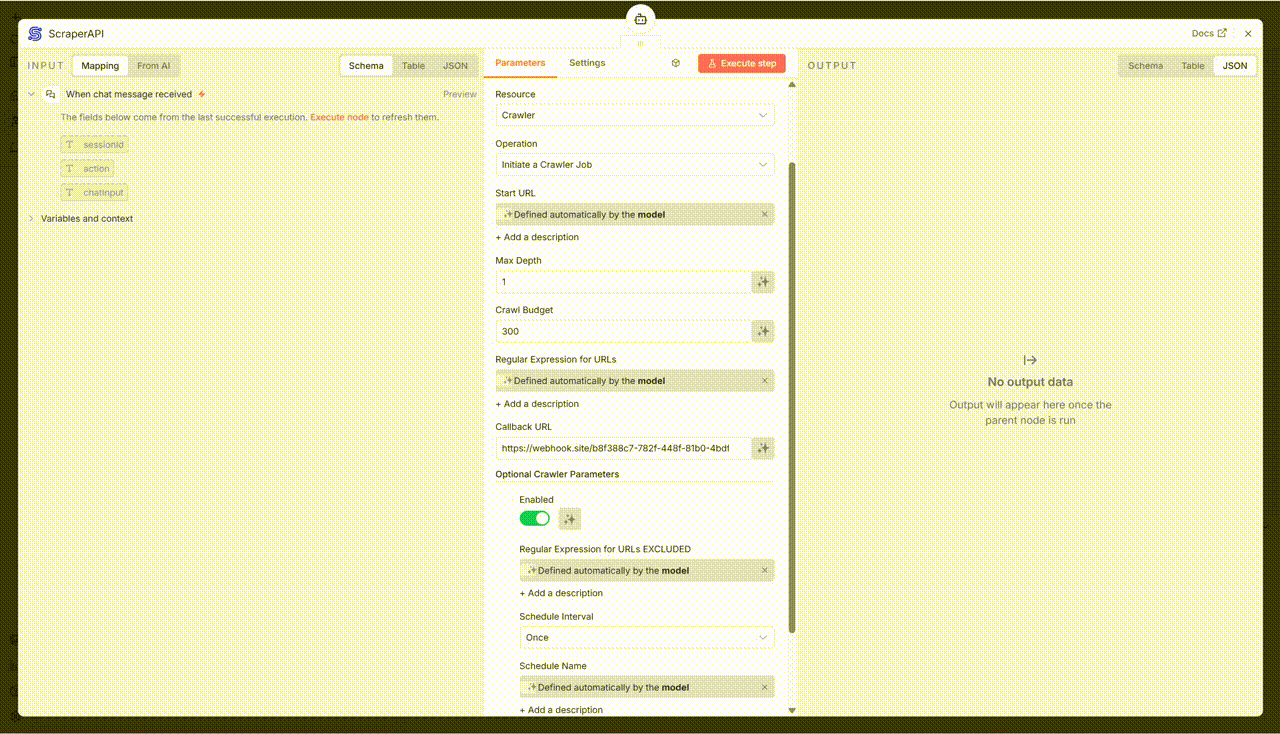
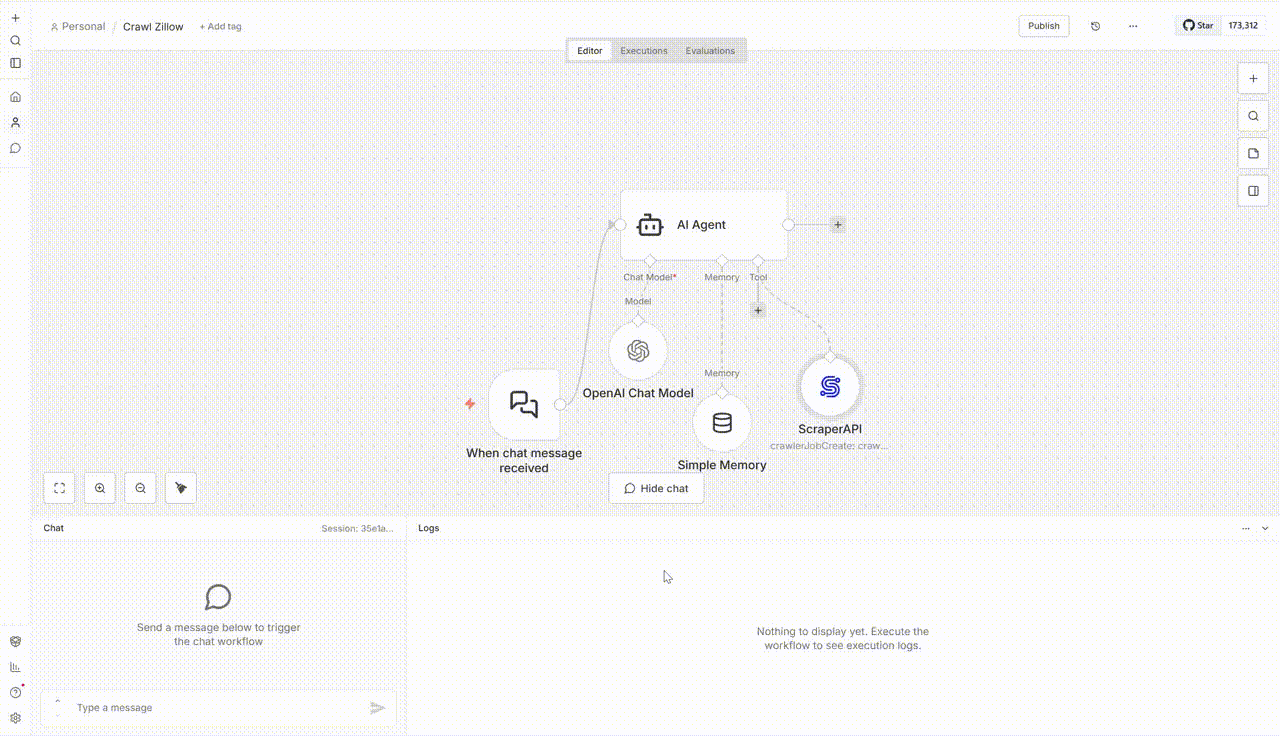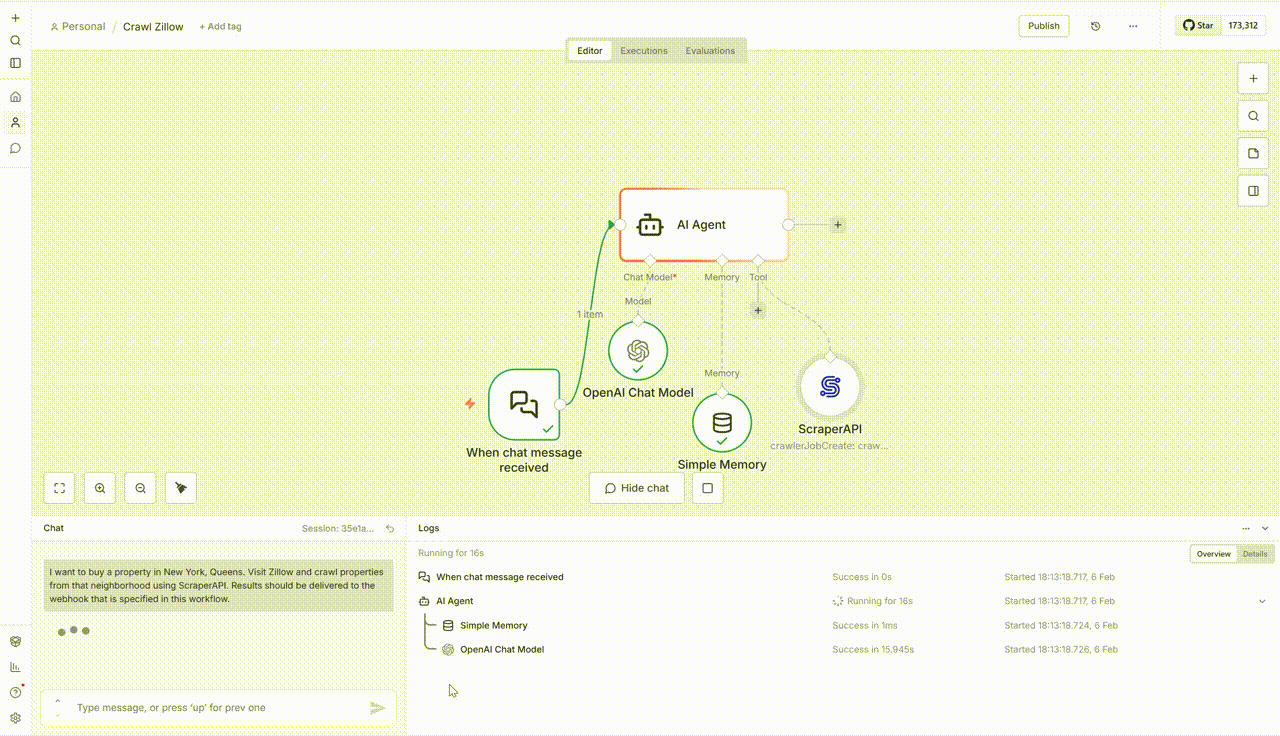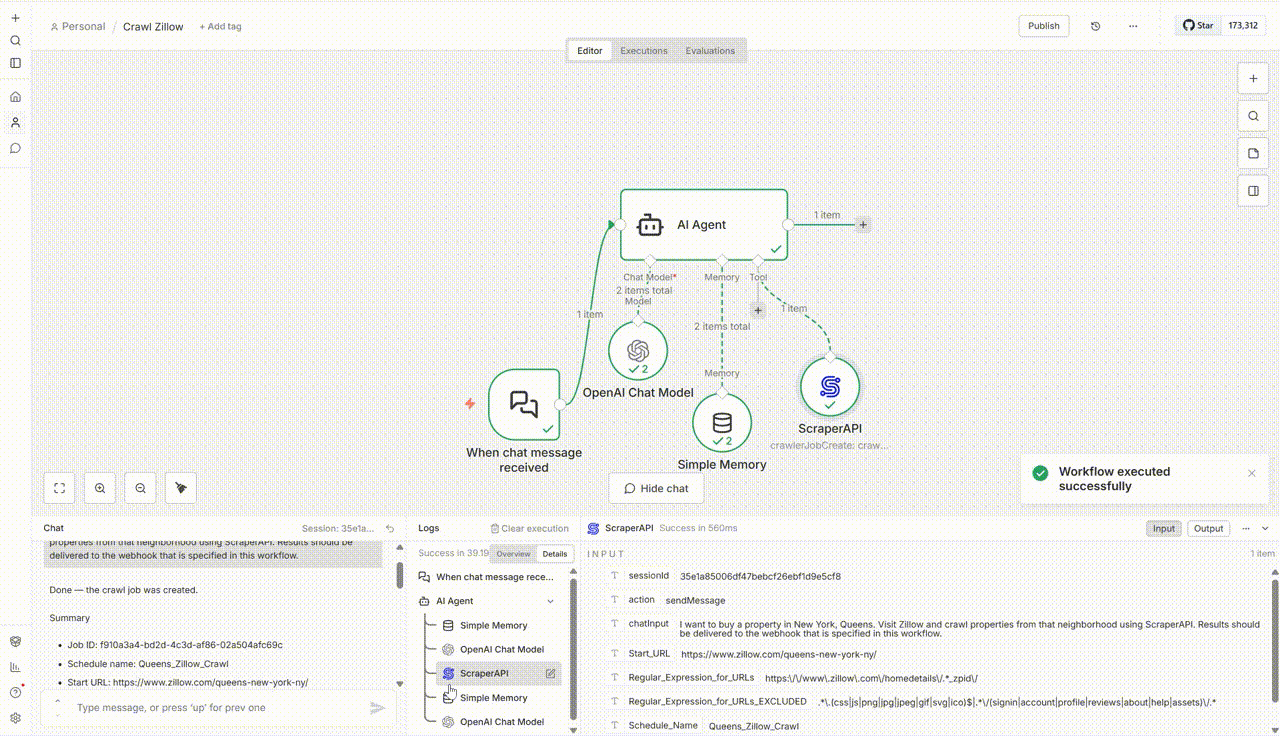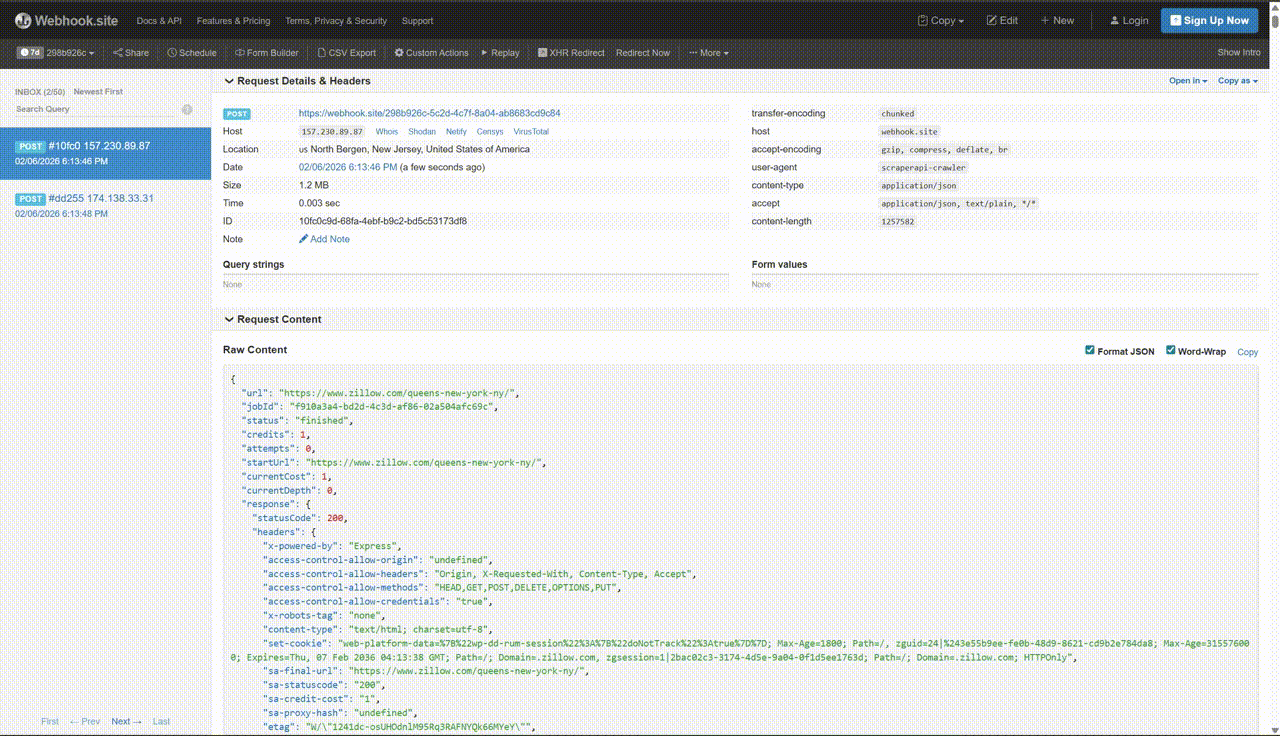
Integrating an AI Chat Model into your workflow unlocks prompt-driven crawling, allowing you to initiate crawls using natural language.
* Add a **Chat Message Received** trigger.
* Add an **AI Agent** node.
* Connect an **AI Chat Model** (e.g. OpenAI) node to the Agent (Chat Model input).
* Connect a **Simple Memory** node to the Agent (Memory input).
* Connect the **ScraperAPI** node to the Agent (Tool input).
* Add a **system prompt** to the **AI Agent** explaining how it should behave.
The example below demonstrates how to use the ScraperAPI Crawler with n8n to crawl real estate website listings and find properties in Queens, New York using natural language.
---
# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.
## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.
Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:
```
GET https://docs.scraperapi.com/integrations/automation-and-workflow-integrations/n8n-integration/scraperapi-crawler-n8n.md?ask=&goal=
```
`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.
The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.
Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.